OKHK 👀

  1. https://github.com/shadow1ng/fscan GitHub - shadow1ng/fscan: 一款内网综合扫描工具,方便一键自动化、全方位漏扫扫描。(An intranet comprehensive scanning tool, enabling one-click automated, all…

  2. 代码,大家可以照着这个自己玩

    Forwarded from yihong0618 和朋友们的频道 (伊)
    代码,大家可以照着这个自己玩。因为写的比较快,🔒糙极了(又不是不能用)
    https://github.com/yihong0618/tg_bot_collections
    
    from telebot import TeleBot
    from telebot.types import Message
    
    from . import *
    
    import wave
    import numpy as np
    from handlers.ChatTTS import Chat
    
    chat = Chat()
    chat.load_models()
    is_generating = False
    
    
    def generate_tts_wav(prompt):
        global is_generating
        texts = [prompt,]
        is_generating = True
        wavs = chat.infer(texts, use_decoder=True)
        output_filename = 'tts.wav'
        audio_data = np.array(wavs[0], dtype=np.float32)  # Ensure the data type is correct
        sample_rate = 24000
        # Normalize the audio data to 16-bit PCM range
        audio_data = (audio_data * 32767).astype(np.int16)
    
        # Open a .wav file to write into
        with wave.open(output_filename, 'w') as wf:
            wf.setnchannels(1)  # Mono channel
            wf.setsampwidth(2)  # 2 bytes per sample
            wf.setframerate(sample_rate)
            wf.writeframes(audio_data.tobytes())
    
        print(f"Audio has been saved to {output_filename}")
        is_generating = False


    def tts_handler(message: Message, bot: TeleBot):
        """pretty tts: /tts <address>"""
        global is_generating
        if is_generating:
            bot.reply_to(message, "please wait for the previous ChatTTS to finish")
            return
        bot.reply_to(
            message,
            f"Generating ChatTTS may take some time please left" 
        )
        m = message.text.strip()
        prompt = m.strip()
        if len(prompt) > 100:
            bot.reply_to(message, "prompt too long must length < 100")
            return
        try:
            generate_tts_wav(prompt)
            with open(f"tts.wav", "rb") as audio:
                bot.send_audio(
                    message.chat.id, audio, reply_to_message_id=message.message_id
                )
        except Exception as e:
            print(e)
            bot.reply_to(message, "tts error")
            is_generating = False
    
    
    def register(bot: TeleBot) -> None:
        bot.register_message_handler(tts_handler, commands=["tts"], pass_bot=True)
        bot.register_message_handler(tts_handler, regexp="^tts:", pass_bot=True)

  3. 当时 reverse ChatGPT edge 等等的天才少年好像买了 Mac...对 Mac 出手了

    Forwarded from yihong0618 和朋友们的频道 (伊)
    当时 reverse ChatGPT edge 等等的天才少年好像买了 Mac...对 Mac 出手了
    https://github.com/acheong08/apple-wps-api GitHub - acheong08/apple-corelocation-experiments: Experimenting with Apple's WPS location service

  4. https://github.com/ngc660sec/NGCBot GitHub - ngc660sec/NGCBot: 一个基于✨HOOK机制的微信机器人,支持🌱安全新闻定时推送【FreeBuf,先知,安全客,奇安信攻防社区】,👯Kfc文案,⚡漏洞查询,⚡手机号归属地查询,⚡知识库查询,🎉星座查询,⚡天气查询,🌱摸鱼日历,⚡微步威胁情报查询,…

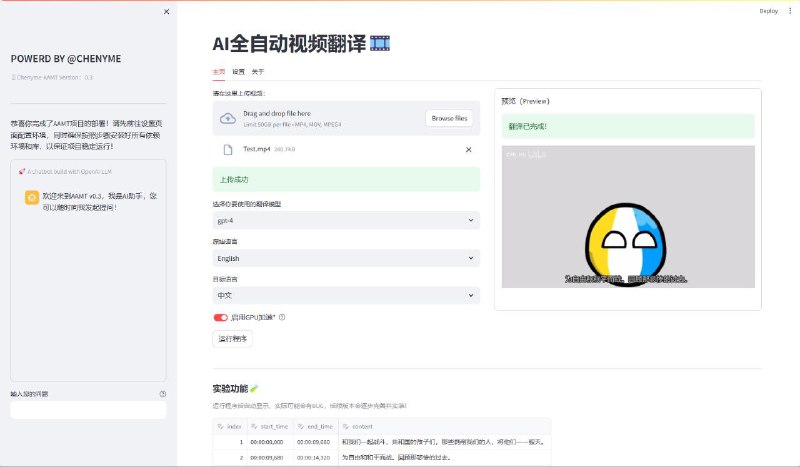
  5. Chenyme AAVT - 全自动视频/音频翻译工具

    Chenyme AAVT - 全自动视频/音频翻译工具

    https://github.com/Chenyme/Chenyme-AAVT

    一个简单易用的全自动视频(音频)识别、翻译工具,快速识别声音并翻译生成字幕文件,然后将翻译后的字幕与原视频合并,生成翻译后的视频。

    主要基于 OpenAI 开发的 Whisper 来识别声音和 LLMs 辅助翻译字幕 ,利用 Streamlit 搭建快速使用的 WebUI 界面,以及 FFmpeg 来实现字幕与视频的合并。

    #AI #Tool #Video #GitHub

  6. 当打开 ChatGPT macOS App 时出现 "Coming soon - You do not have access to the desktop app yet" 时的破解方法:

    当打开 ChatGPT macOS App 时出现 "Coming soon - You do not have access to the desktop app yet" 时的破解方法:

    1、下载登陆ChatGPT客户端 brew install --cask chatgpt

    2、登陆ChatGPT客户端账户

    3、在未出现“无法使用”的提示之前,快速按下「command + Q」

    4、重新打开ChatGPT客户端就可以使用了!
    #RePost #AI #Apple #macOS
    ref: https://vxtwitter.com/imxiaohu/status/1791831563837358127

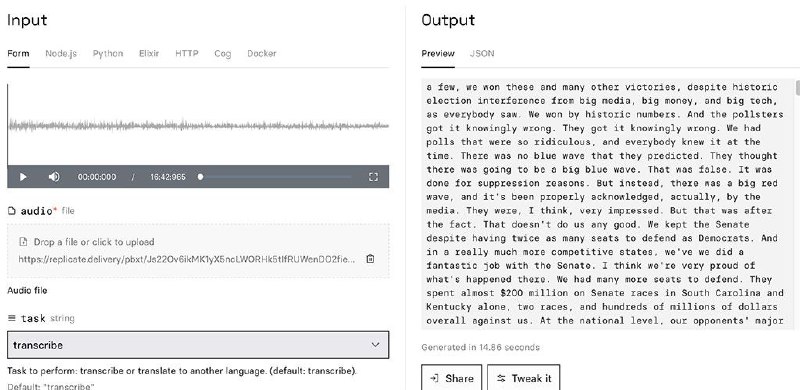
  7. Insanely Fast Whisper - 音频转文字工具

    Insanely Fast Whisper - 音频转文字工具

    https://github.com/Vaibhavs10/insanely-fast-whisper

    https://replicate.com/vaibhavs10/incredibly-fast-whisper

    一个基于 OpenAI Whisper Large v3 模型的高速音频转文字工具,能够在不到 98 秒的时间内转录 300 分钟(5小时)音频。

    适用于多场景,支持 100 种语言的转录并支持翻译功能,提供按词或片段生成时间戳文本,方便字幕制作。

    提供命令列界面(CLI),也可以通过 Whisper API 进行线上语音转文字。

    #Voice #AI #GitHub #Tool